← Daily Brief for September 20, 2026
NVIDIA AIPerf targets LLM benchmarking bottlenecks at high concurrency
Focus: Technical AI Engineering
Date: September 18, 2026
Topics: LLM inference, benchmarking, performance engineering
Evidence: Official Announcement
Availability: Published
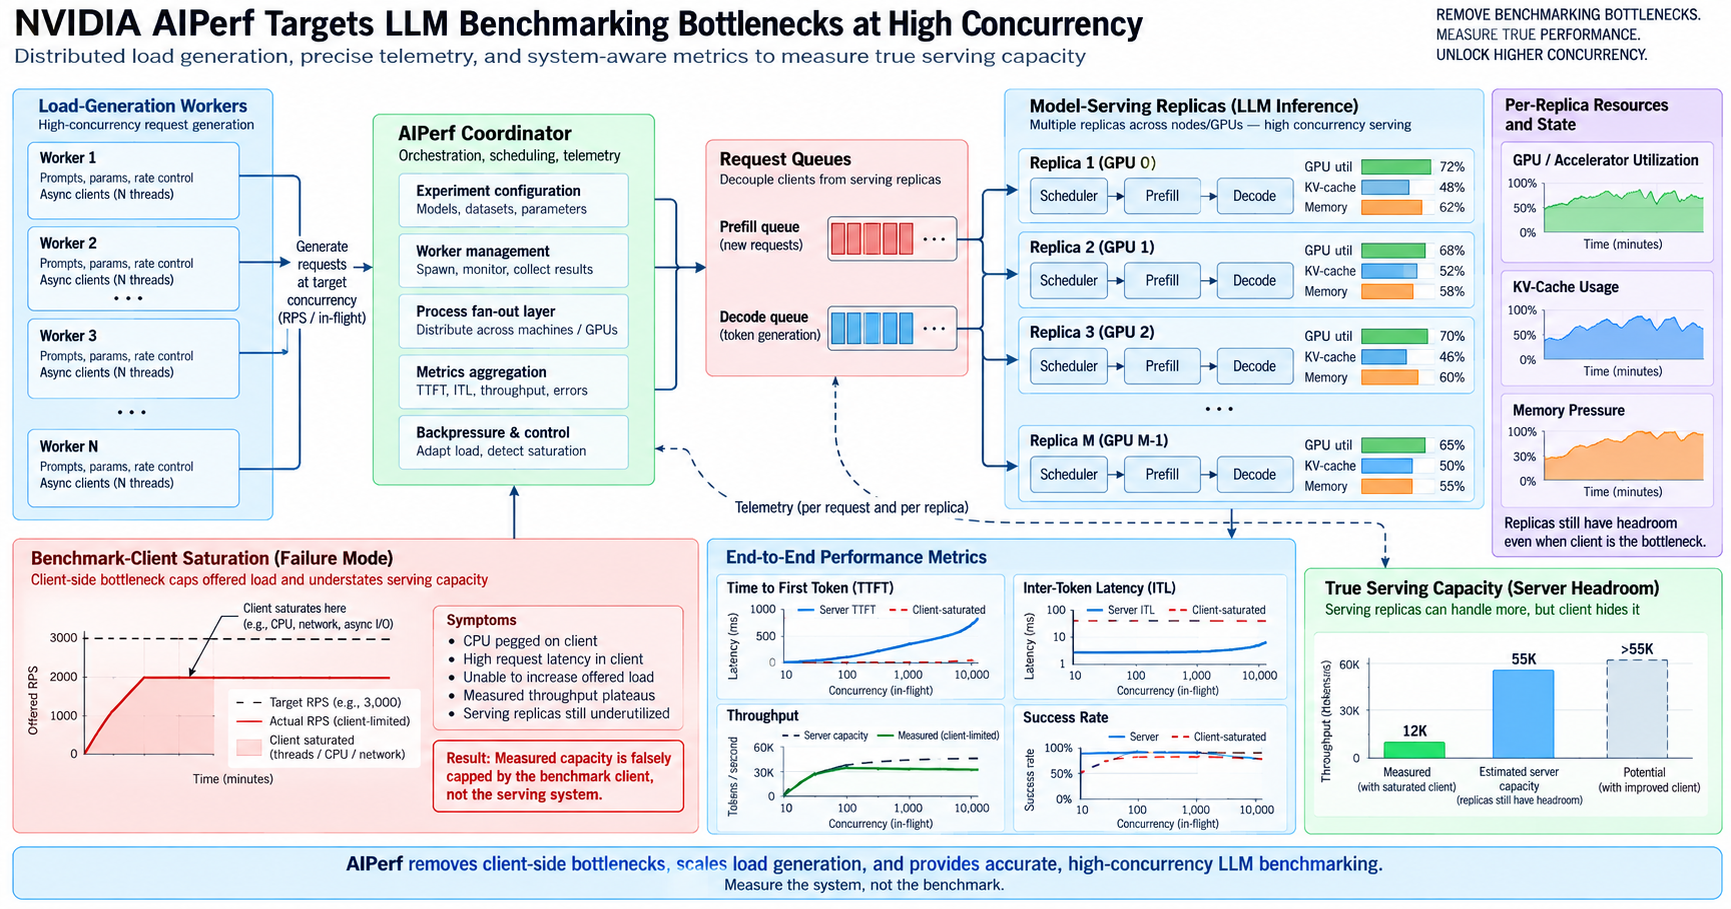
Summary: NVIDIA introduced AIPerf as the successor to GenAI-Perf, using a multiprocess architecture intended to prevent the benchmark client itself from becoming the bottleneck during high-concurrency LLM inference tests.
Why it matters: When benchmarking tools saturate before the model-serving stack does, engineering teams can draw the wrong conclusions about capacity. A benchmark designed for larger concurrency makes infrastructure tuning and deployment comparisons more trustworthy.
What to do now
Recheck inference benchmarks: If current load tests approach client-side limits, compare AIPerf with the existing harness before using benchmark results for capacity decisions.
Source: Benchmarking LLM Inference at Scale with AIPerf