← Daily Brief for September 12, 2026
A hands-on no-code agent comparison shows that fit depends on the whole workflow
Focus: Agents for Non-Technical People
Date: September 11, 2026
Topics: no-code agents, workflow evaluation, debugging, failure handling
Evidence: Practitioner Analysis
Availability: Not Applicable
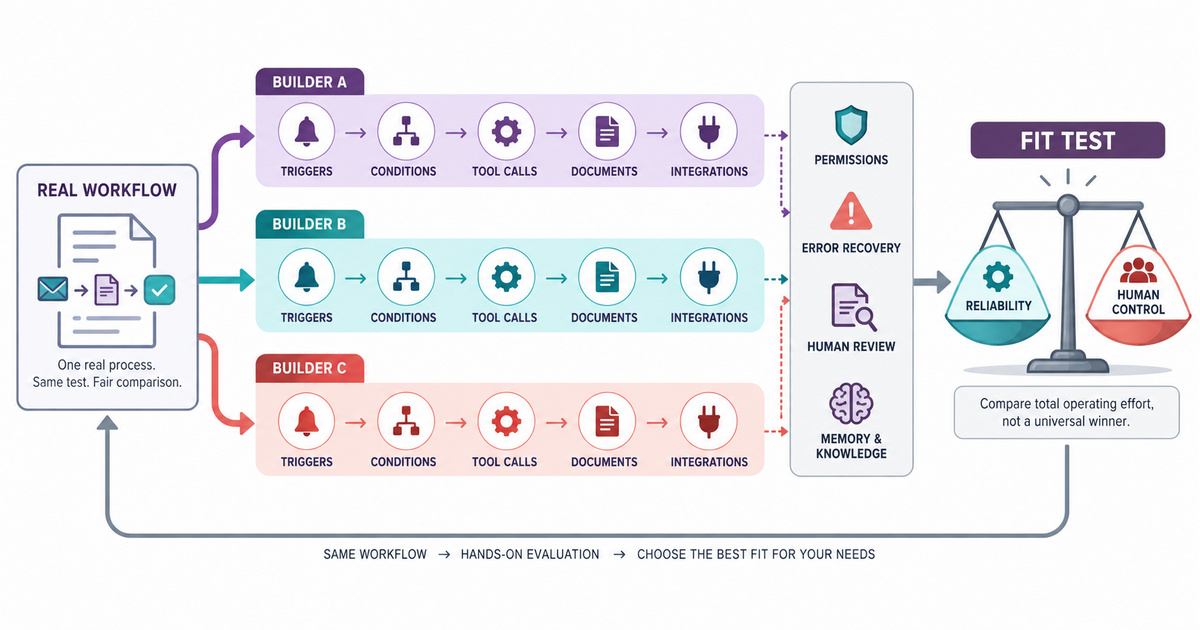
Summary: AIMultiple updated its hands-on comparison after spending three days configuring agent workflows across n8n, Make, Zapier, and a Creatio trial, while evaluating OpenAI AgentKit from documentation. The comparison examines triggers, conditional steps, tool calls, webhooks, debugging visibility, self-hosting, integrations, and different execution-, operation-, task-, or model-consumption cost structures.
Why it matters: A low-code canvas does not remove engineering tradeoffs: the meaningful unit is an end-to-end workflow with permissions, observability, error paths, review, and a cost model. The article mixes direct testing with vendor documentation, was updated September 11 while some tabular data carries older timestamps, and should guide a proof-of-concept rather than declare a universal winner.
What to do now
Run a two-builder fit test: Use one workflow, identical acceptance criteria, an injected failure, and total operating effort to compare platforms.
Source: Low/No-Code AI Agent Builders: n8n, make, Zapier