← Daily Brief for November 5, 2026
A review loop turns expert judgment into stronger agent evaluations
Focus: Agents for Everyone
Date: November 3, 2026
Topics: Human review, Evaluation rubrics, Golden datasets
Evidence: Publisher Authored
Availability: Available
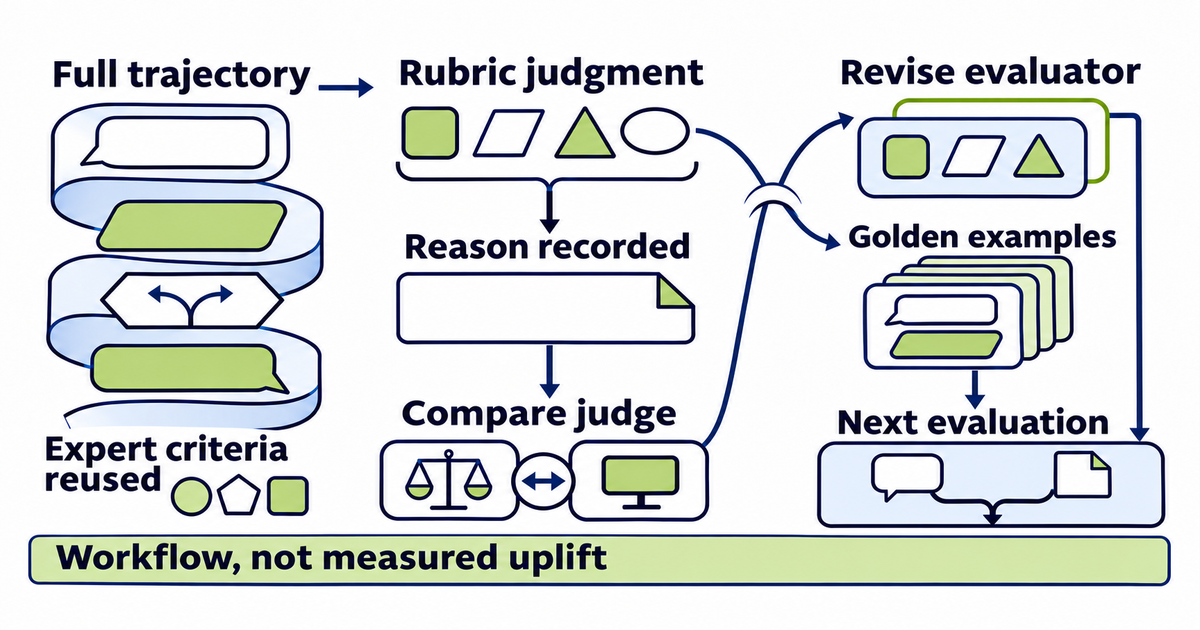
Summary: LangChain proposes a human-review loop for agent trajectories: inspect the full thread, score it against a rubric with a reason, compare that judgment with an automated evaluator, revise the evaluator, and promote strong examples into a golden dataset. The vendor-authored workflow is practical but not independently benchmarked.
Why it matters: Domain experts can apply this reusable skill to one noncoding workflow. Review complete trajectories, record rubric-based reasons, reconcile disagreements with the automated judge, and add only verified examples to a golden set before expanding evaluation coverage.
Source: Human insight is the strategic advantage for agents