Daily Generative AI Brief — November 5, 2026
Published: November 5, 2026
Coverage period: November 2–4, 2026
IN THIS EDITION · 6 ARTICLES / 2 VIDEOS / 2 PODCASTS
Choose what matters to your work
- Cloudflare adds per-agent access policies for personal assistantsArticle · about 7 min source read
- A review loop turns expert judgment into stronger agent evaluationsArticle · about 8 min source read
- OpenAI plans to acquire Pierre for interface-driven codingArticle · about 7 min source read
- Databricks argues for governed open-weight model portfoliosArticle · about 8 min source read
- FlashProve makes model identity cryptographically checkableArticle · about 11 min source read
- NVIDIA turns agent failure traces into executable evaluationsArticle · about 8 min source read
- A plan to stop AI from automating our declineVideo · 15:51
- AI leaders fuel calls to rein in rapidly advancing techVideo · 8:34
- The 2026 Software Factory Standard — Zach Lloyd, Warp.devPodcast · 35:00
- The Inside Story of the 150 People Who Built Modern AIPodcast · 46:14
1. Cloudflare adds per-agent access policies for personal assistants
Focus: Agents for Everyone
Date: November 4, 2026
Topics: Agent identity, Access policies, Action control
Evidence: Publisher Authored
Availability: Available
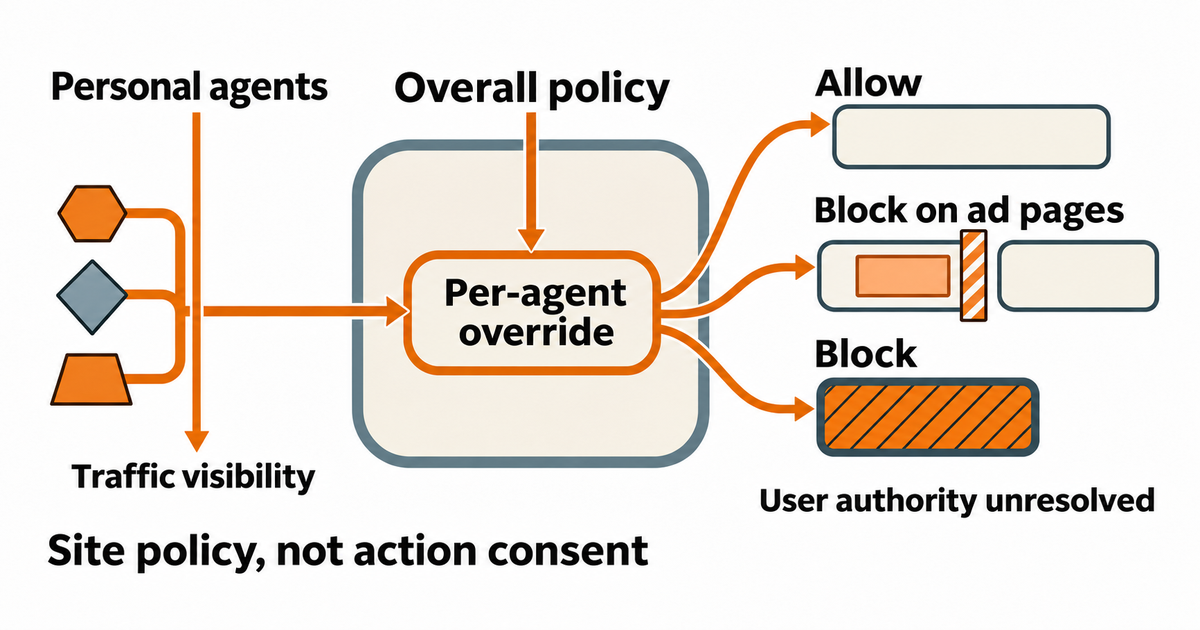
Summary: Cloudflare introduced a Personal Assistants category, visibility tooling and per-agent access policies for consumer AI assistants reaching corporate resources. The company positions the controls as early access and emphasizes identity, reputation and accountability gaps when agents act for users. The announcement provides product behavior, not independent outcome measurements.
Why it matters: Security teams can inventory one assistant-mediated workflow, identify the user and agent separately, restrict reachable resources, and require confirmation for consequential actions. Log every decision so the policy can be tested against misuse, stale identity and exception handling.
Source: Personal agents need visibility and control
2. A review loop turns expert judgment into stronger agent evaluations
Focus: Agents for Everyone
Date: November 3, 2026
Topics: Human review, Evaluation rubrics, Golden datasets
Evidence: Publisher Authored
Availability: Available
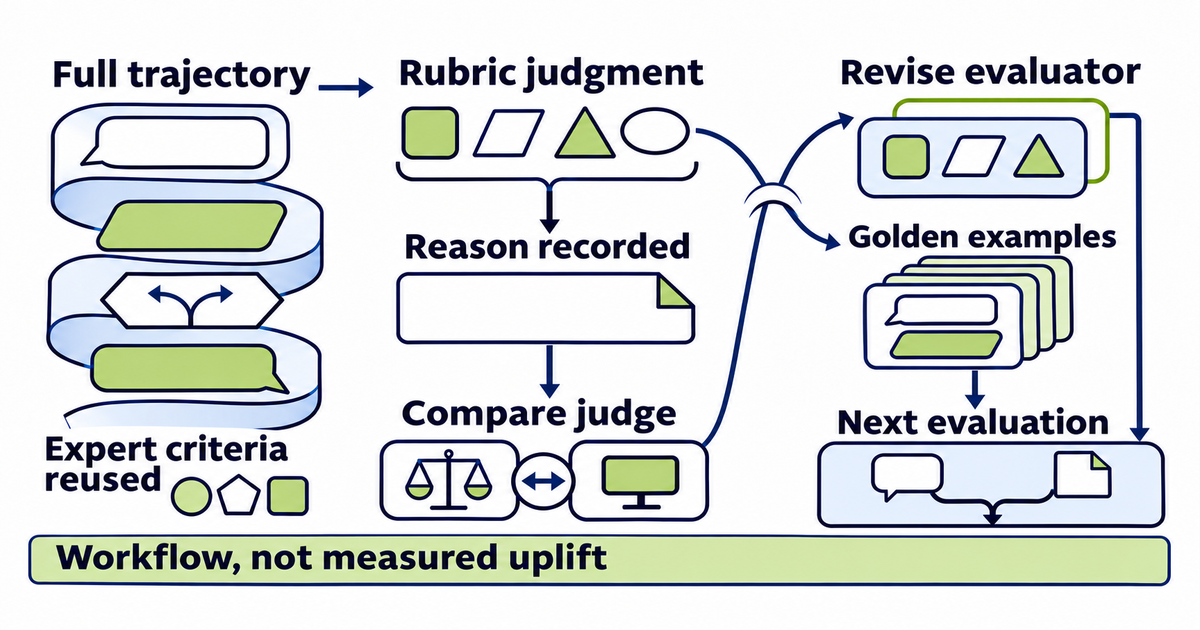
Summary: LangChain proposes a human-review loop for agent trajectories: inspect the full thread, score it against a rubric with a reason, compare that judgment with an automated evaluator, revise the evaluator, and promote strong examples into a golden dataset. The vendor-authored workflow is practical but not independently benchmarked.
Why it matters: Domain experts can apply this reusable skill to one noncoding workflow. Review complete trajectories, record rubric-based reasons, reconcile disagreements with the automated judge, and add only verified examples to a golden set before expanding evaluation coverage.
Source: Human insight is the strategic advantage for agents
3. OpenAI plans to acquire Pierre for interface-driven coding
Focus: Applied Generative AI for Knowledge Workers
Date: November 4, 2026
Topics: Coding interfaces, Parallel agents, Acquisition status
Evidence: Publisher Authored
Availability: Available
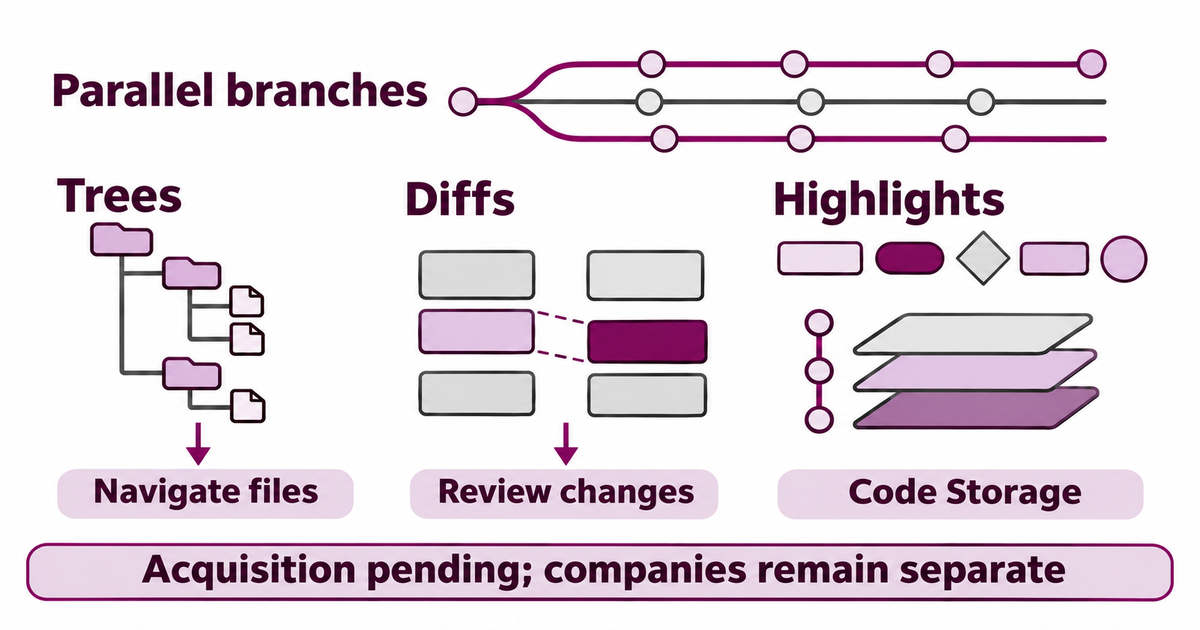
Summary: OpenAI says it has agreed to acquire Pierre, whose Trees, Diffs, Highlights and Code Storage interfaces organize parallel coding-agent work. The transaction remains subject to closing conditions and regulatory approval, and Pierre stays separate until closing. Open-source projects will remain open source according to the announcement.
Why it matters: Knowledge-work teams can evaluate the workflow without treating the deal as complete: compare one multi-agent review task using branches, diffs and highlighted changes, then measure review time, missed conflicts and the cost of switching context.
Source: OpenAI to acquire Pierre
4. Databricks argues for governed open-weight model portfolios
Focus: Applied Generative AI for Knowledge Workers
Date: November 4, 2026
Topics: Open weights, Model governance, Portfolio testing
Evidence: Publisher Authored
Availability: Available
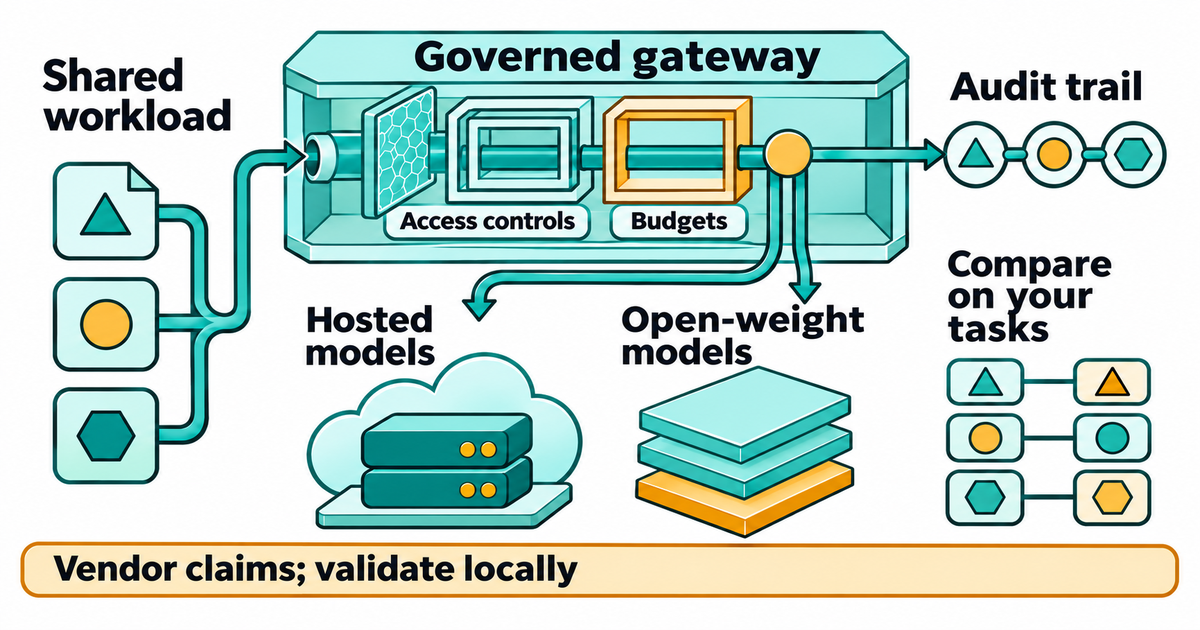
Summary: Databricks outlines seven pressures pushing enterprises toward open-weight models, including cost control, data locality, customization and reduced provider dependence. The article recommends gateways, evaluation harnesses and governance across a model portfolio. Its advantages and economics are vendor-authored claims, so teams should validate them against their own workloads.
Why it matters: Procurement and platform teams can turn the article into a bounded comparison: run the same private workload through one hosted and one open-weight option, then record quality, latency, operating cost, data handling and rollback complexity.
Source: The Enterprise Case for Open Weight Models
5. FlashProve makes model identity cryptographically checkable
Focus: Technical AI Engineering
Date: November 2, 2026
Topics: Provable inference, Model identity, Zero-knowledge proofs
Evidence: Publisher Authored
Availability: Available
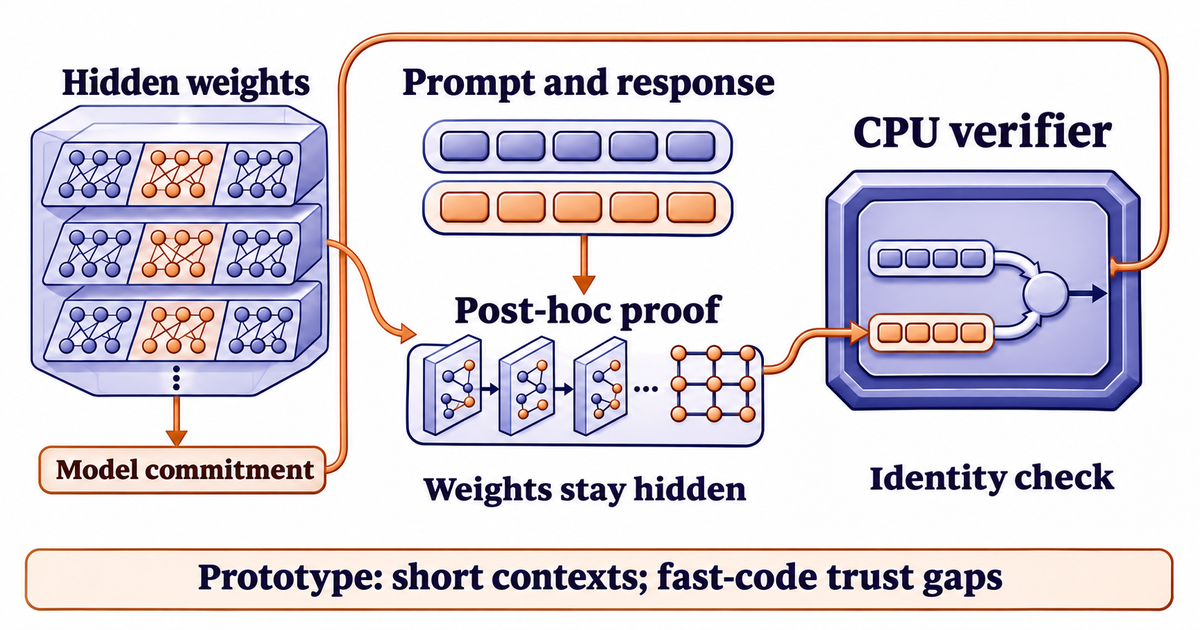
Summary: Anthropic released FlashProve, an open-source prototype that attaches cryptographic proofs to model outputs so a verifier can check which committed weights produced them without seeing those weights. The team reports 110 proved tokens per second for a quantized 400-billion-parameter mixture-of-experts model, while documenting substantial compute overhead, short contexts, greedy decoding and executable-code trust gaps.
Why it matters: Engineering teams can evaluate provable inference as an integrity layer, not a blanket safety guarantee. Reproduce one proof, audit the verifier and formal statements, measure latency and proof size, and document what model identity checks still cannot establish.
Source: Progress on provable inference for large language models
6. NVIDIA turns agent failure traces into executable evaluations
Focus: Technical AI Engineering
Date: November 4, 2026
Topics: Trace evaluation, Harness repair, Held-out tests
Evidence: Publisher Authored
Availability: Available
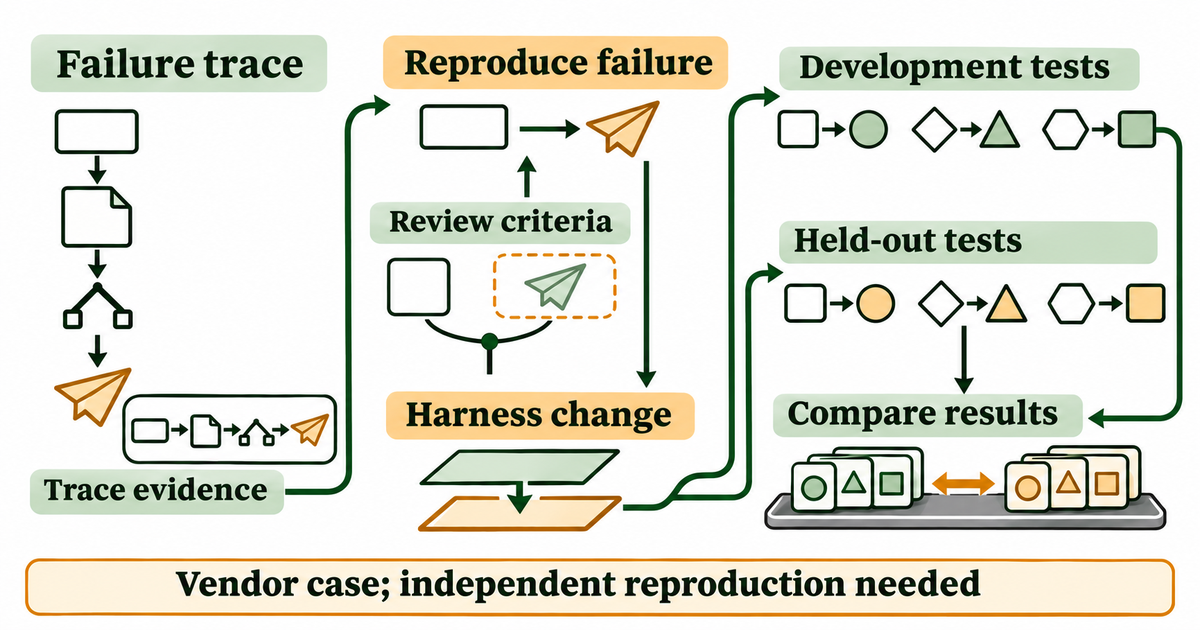
Summary: NVIDIA describes a NeMo Compass workflow that converts failed agent traces into Harbor or NeMo Gym evaluations, repairs the harness, and reruns development plus held-out tests. Its vendor case study reports fewer malformed tool calls, better scores, and lower tool use across six scenarios; those results require independent reproduction.
Why it matters: The useful pattern is trace-to-test discipline, not the reported uplift. Teams can preserve a failure, generate a minimal evaluation, fix the harness, and verify both development and held-out cases before promoting an agent update.
Source: Use NVIDIA NeMo to Turn Agent Failures Into Tests and Harness Fixes
Worth Watching
7. General
A plan to stop AI from automating our decline
Open the permanent video page
Channel: TED
Date: April 1, 2026
Duration: 15:51 · Longer selection today: no suitable video of 10 minutes or less was found.
Format: Video
Summary: Gina Raimondo argues that AI workforce policy should combine employer-defined skills, apprenticeships, continuous learning, wage insurance and support for self-employment. The complete TED transcript presents a policy position rather than settled evidence. The April original date and consecutive-day TED exposure remain explicit advisories, while the exact program is archive-new.
Why it matters: Leaders can convert the policy argument into a transition checklist: identify changing tasks, specify teachable skills, fund retraining and redeployment, protect displaced workers and test whether incentives improve durable employment outcomes.
Source: Watch on TED
8. Agents for Everyone
AI leaders fuel calls to rein in rapidly advancing tech
Open the permanent video page
Channel: PBS NewsHour
Date: September 14, 2026
Duration: 8:34
Format: Video
Summary: PBS NewsHour interviews journalist Stephen Witt about calls from AI leaders to slow development, reported security incidents and proposals for independent oversight. The complete official transcript keeps extraordinary claims attributed rather than presenting them as established facts. The September original date and consecutive-day PBS exposure remain explicit editorial advisories.
Why it matters: Readers can separate attributed forecasts from documented incidents, then ask for independent evidence, containment details, responsible operators and regulatory scope before treating a dramatic warning as a verified account of system capability.
Source: Watch on PBS NewsHour
Worth Listening — Podcasts
9. The 2026 Software Factory Standard — Zach Lloyd, Warp.dev
Open the permanent podcast page
Show: Latent Space
Focus: Agents for Everyone
Date: November 3, 2026
Duration: 35:00
Summary: Latent Space interviews Warp CEO Zach Lloyd about software factories, Slack-to-pull-request workflows, cost, throughput, quality and changing engineering roles. The exact Apple episode identity and 35-minute runtime are verified against the show’s current feed, while the complete timecoded transcript preserves vendor claims as attributed statements.
Why it matters: Engineering leaders can turn the interview into a measurement plan: define one factory workflow, record cost per accepted change, review burden and defect escape, and compare it with the existing process before expanding autonomy.
Coverage: Selected for this edition.
Listen / watch: Latent Space
10. The Inside Story of the 150 People Who Built Modern AI
Open the permanent podcast page
Show: The Every Podcast
Focus: Agents for Everyone
Date: November 4, 2026
Duration: 46:14
Summary: The Every Podcast interviews journalist Kevin Roose about documenting modern AI, mandatory safety testing, research methods, AI-assisted editing and deciding which tasks should remain human. The exact first-party episode page and complete timecoded transcript support the 46:14 program; claims about laboratories, regulation and tools remain attributed.
Why it matters: Knowledge workers can use the interview’s weightlifting-versus-forklifting test to decide which tasks build judgment through effort, which are safe to delegate, and where human sourcing, coaching, accountability or independent verification must remain.
Coverage: Selected for this edition.
Listen / watch: The Every Podcast
Emerging AI Watchlist
1 new today · 1 updated · 41 carried forward. 1 archived / dropped recently.
New today:
- Long-horizon state tracking benchmarks
Updated today:
- Consumer agent task permissions
Carried forward: 41
Archived / dropped recently:
- Native multimodal world simulation — Carried forward after the October 29 review found no material evidence change requiring a new assessment.
Help choose what we investigate next. Explore emerging ideas and tell us which interest you.
Editorial takeaway
Engineering teams can evaluate provable inference as an integrity layer, not a blanket safety guarantee. Reproduce one proof, audit the verifier and formal statements, measure latency and proof size, and document what model identity checks still cannot establish.