← Daily Brief for November 4, 2026
StateBench exposes long-horizon tracking failures
Focus: Technical AI Engineering
Date: November 3, 2026
Topics: State tracking, Finite systems, Long horizons
Evidence: Publisher Authored
Availability: Available
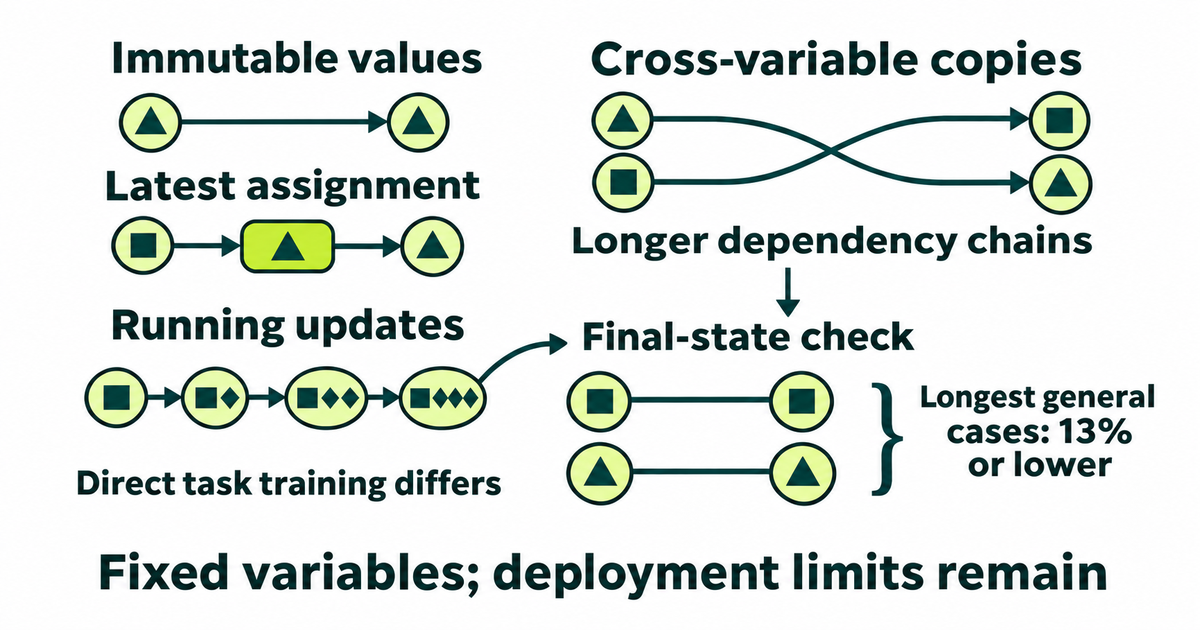
Summary: Ai2’s StateBench tests whether language models can track evolving states across long sequences in six finite-system tasks. The authors report that frontier models fall to 13% accuracy or less on the longest general cases, while directly trained recurrent and hybrid models generalize farther under the benchmark’s fixed-variable conditions.
Why it matters: Long tool chains and agent workflows depend on remembering what changed, not merely generating plausible next steps. Use this benchmark pattern to stress-test state transitions, while noting that fixed variable counts and numerical precision leave important deployment conditions untested.
Source: StateBench: A Benchmark for State Tracking