← Daily Brief for October 24, 2026
IBM keeps interpretability hooks compatible with high-performance vLLM execution
Focus: Technical AI Engineering
Date: October 21, 2026
Topics: Runtime interpretability, Graph replay, Inference overhead
Evidence: Publisher Authored
Availability: Available
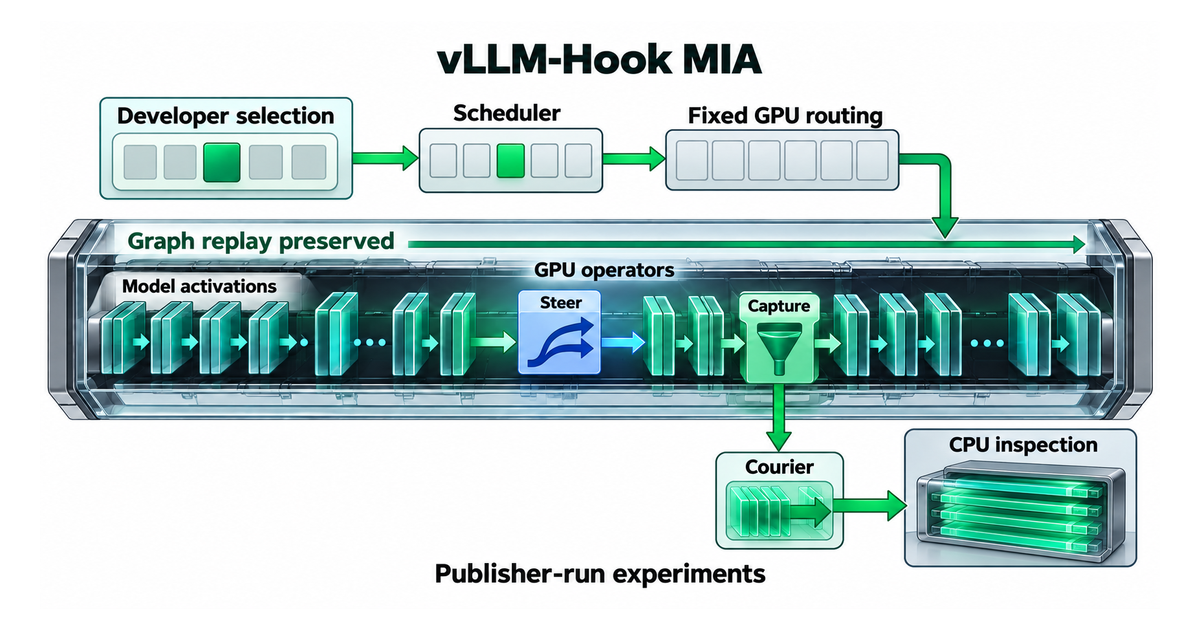
Summary: IBM Research introduces vLLM-Hook, a model-internals access layer that preserves vLLM graph replay while supporting activation inspection and steering. In publisher-run experiments, the team reports up to 20× lower instrumentation overhead than its predecessor, with roughly 2% overhead on small models and 6% on a 70-billion-parameter model.
Why it matters: You will learn where interpretability tooling can distort production inference and how graph-aware hooks reduce that penalty. The reported overhead ranges also provide a practical benchmark for deciding whether observability experiments belong in a serving-path evaluation.
Source: Toward fast AI interpretability and control