← Daily Brief for October 23, 2026
Eight DGX Spark nodes run a 753-billion-parameter model with measured topology trade-offs
Focus: Technical AI Engineering
Date: October 22, 2026
Topics: Desktop AI clusters, Distributed inference, Network topology
Evidence: Publisher Authored
Availability: Available
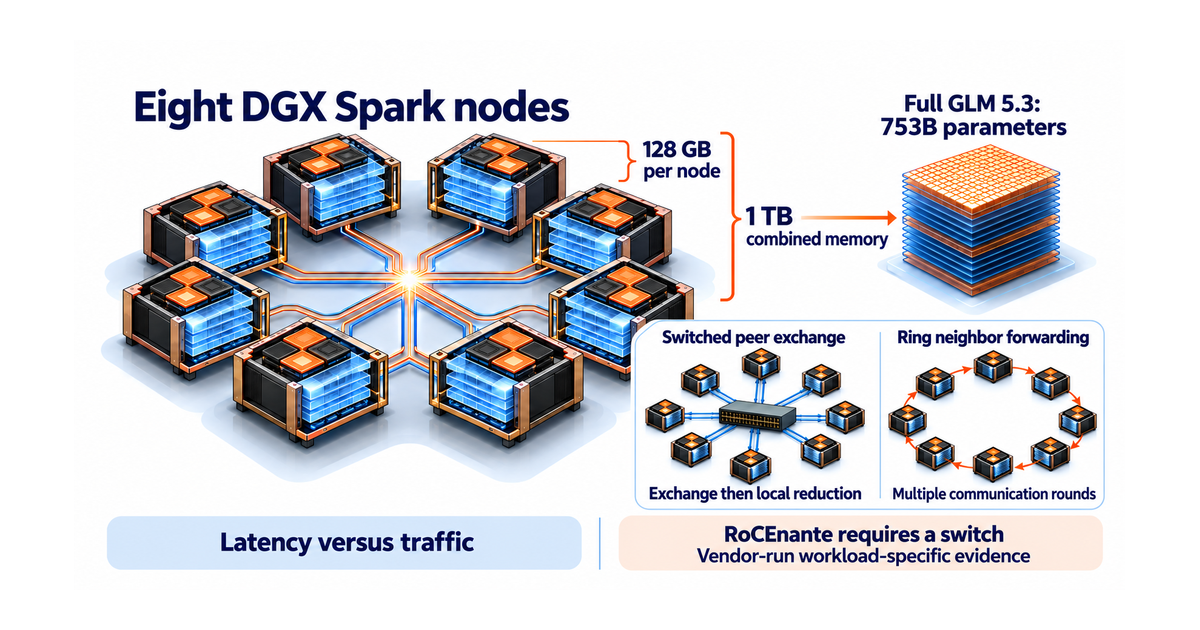
Summary: NVIDIA linked eight DGX Spark systems into a one-terabyte-memory cluster and ran the full 753-billion-parameter GLM 5.3 model. Its published tests show multi-node decode gains and different scaling for switch and ring topologies. The measurements are vendor-run, workload-specific and accompanied by networking, synchronization and memory caveats.
Why it matters: Engineering teams can use the disclosed topology and measurements to design a bounded cluster trial. Readers should compare switch and ring layouts on their own model, recording decode throughput, synchronization overhead, network utilization, memory headroom and failure behavior.
Source: Running Frontier-Class AI Models Across 8 NVIDIA DGX Spark Nodes