← Daily Brief for October 21, 2026
llm-d v1.0 makes inference operations the product
Focus: Technical AI Engineering
Date: October 20, 2026
Topics: Inference operations, KV cache routing, Day-two reliability
Evidence: Publisher Authored
Availability: Available
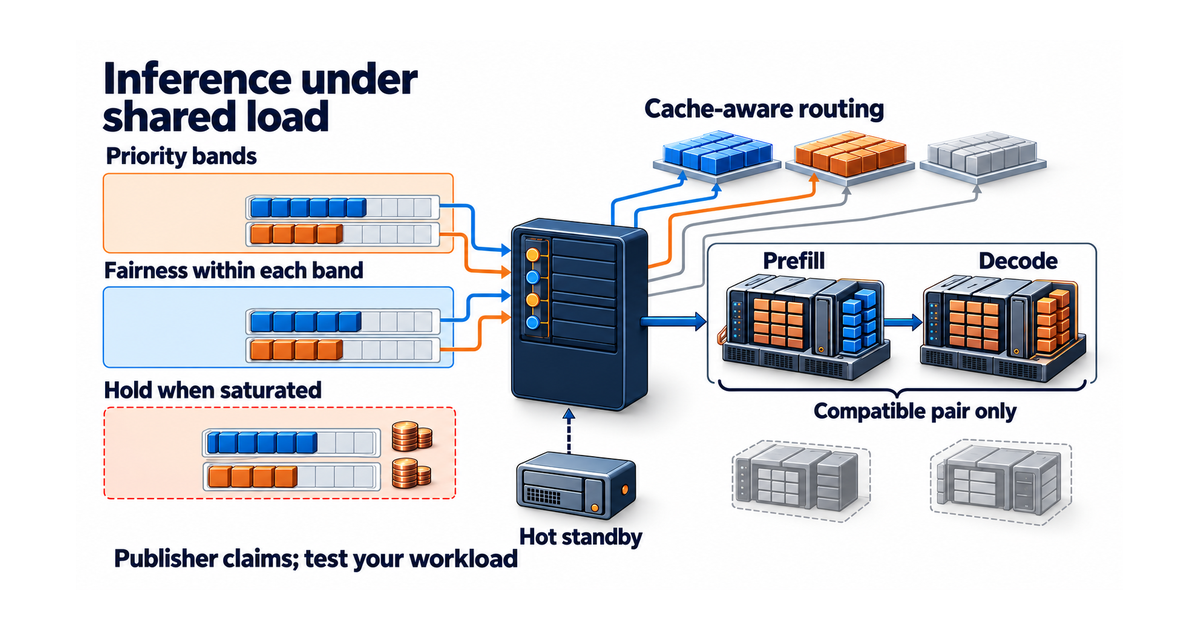
Summary: llm-d v1.0 packages distributed inference for operational use with priority-aware scheduling, multi-tenant fairness, cache-aware routing and zero-downtime updates. The project reports cache-hit improvements from 35% to 70% in one large-scale deployment, while its day-two features focus on predictable service behavior. The figures remain publisher-reported and workload-specific.
Why it matters: Use the release as an operations checklist: test priority fairness, cache routing, rollout safety and failure recovery against your own traffic. Treat the reported cache gains as a hypothesis until reproduced under comparable prompts, hardware and service-level objectives.
Source: llm-d v1.0: State-of-the-Art Inference Ready for Day 2