← Daily Brief for October 18, 2026
A nine-stage evaluation loop catches silent agent failures
Focus: Technical AI Engineering
Date: October 16, 2026
Topics: Agent evaluation, Release gates, Quality drift
Evidence: Publisher Authored
Availability: Available
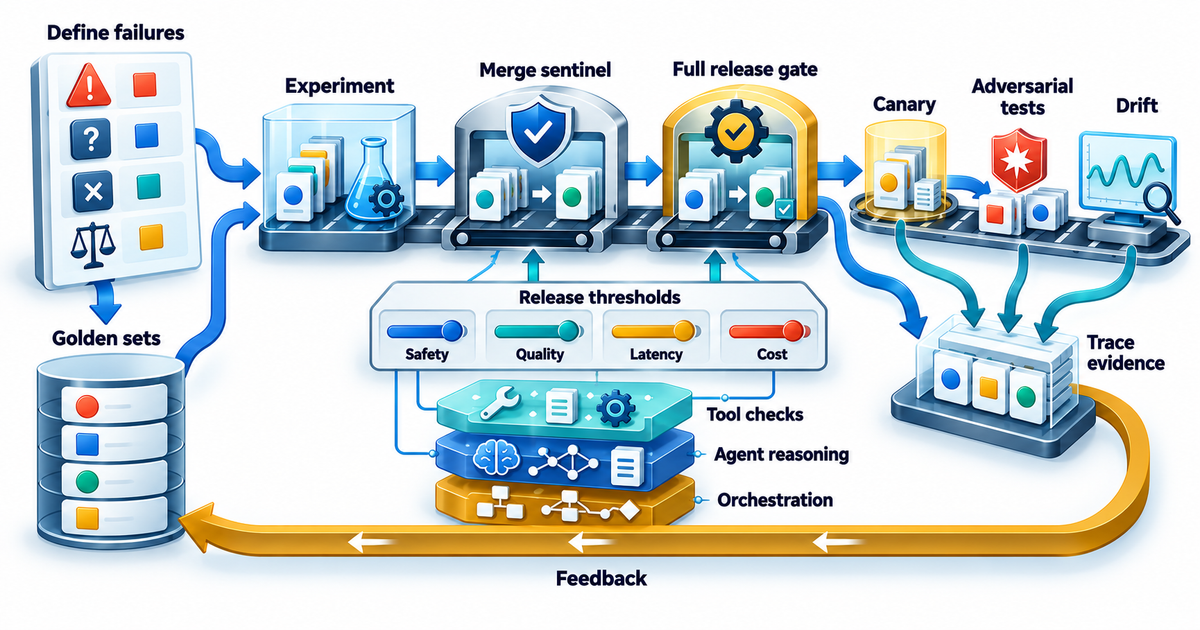
Summary: An AWS production team describes a nine-stage evaluation loop for multi-agent sales analytics, spanning golden sets, merge gates, full release gates, canaries, adversarial tests, drift monitoring and feedback. The team reports that ordinary uptime monitoring missed fluent factual errors, including wrong units, swapped metrics and unsupported calculations, while staged evaluators exposed them before or after release.
Why it matters: Define business failures before choosing evaluators. Build deterministic checks for known facts, task-specific rubrics for ambiguous reasoning and separate tool, agent and orchestration test sets; then block releases when safety, quality, latency or cost crosses an agreed threshold.
Source: Building trust in AI agents: A production-ready evaluation framework with Amazon Bedrock AgentCore